Welcome !
to Kaykobad Reza Blog
Applied Scientist at Amazon | PhD in Multimodal Machine Learning and Computer Vision, UC Riverside
About Me
Featured Post
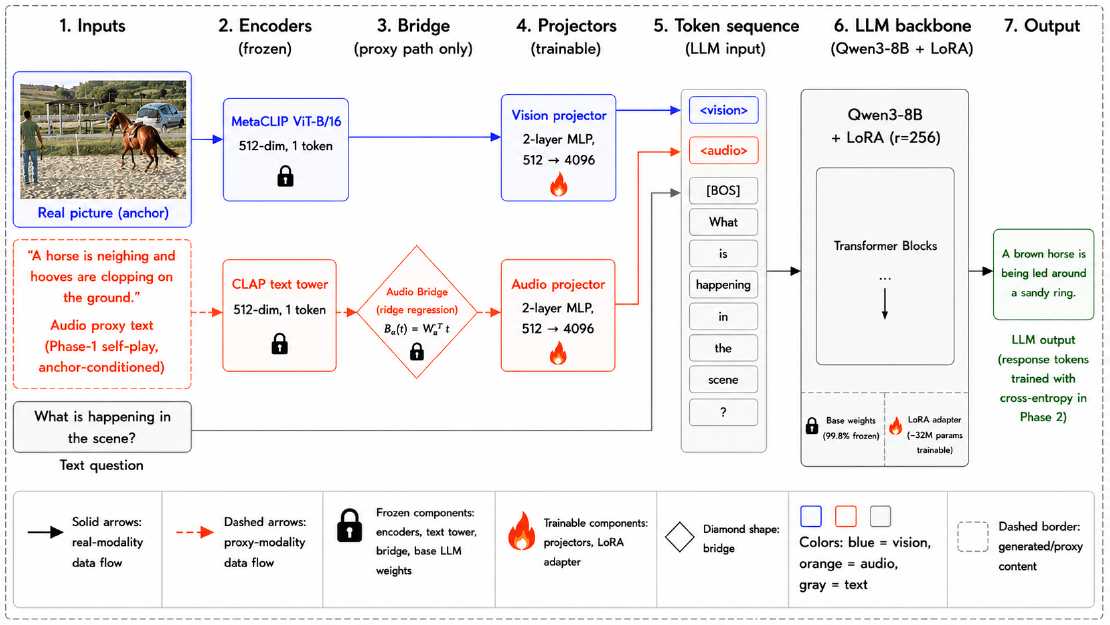
MSP: Modality Self-Play for Training Multimodal LLMs Without Paired Cross-Modal Data
Think about how you understand a video of a dog barking in a park. Your eyes see the dog, your ears hear the bark, and your brain effortlessly puts the two together.
Read more
Recent Post
Hello World, I Am Back!
Hello world, I am back! If you have visited this blog before, you may have noticed that things went quiet for a while.
Read moreMSP: Modality Self-Play for Training Multimodal LLMs Without Paired Cross-Modal Data
Think about how you understand a video of a dog barking in a park. Your eyes see the dog, your ears hear the bark, and your brain effortlessly puts the two together.
Read more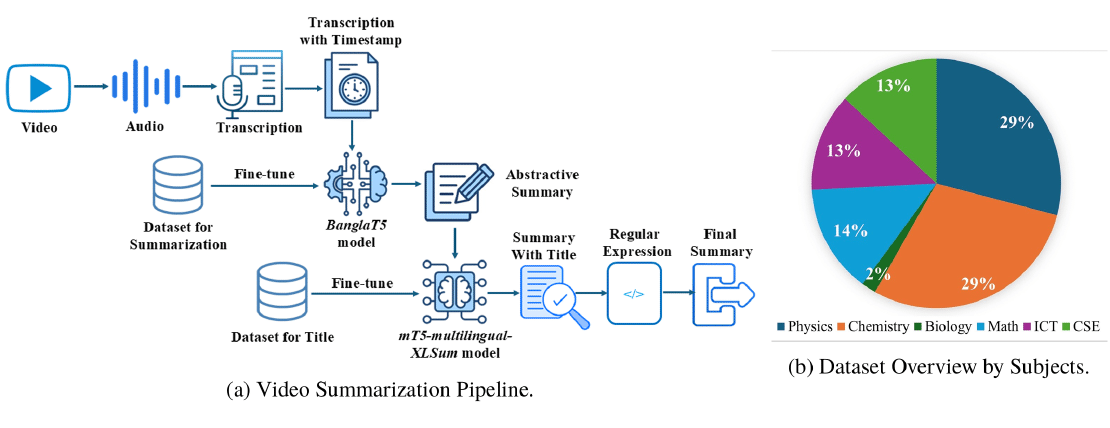
Abstractive Summarization of Bengali Academic Videos Based on Audio Subtitles
Anyone who has studied online knows the feeling. You need one specific explanation from a two-hour lecture, and you end up dragging the progress bar back and forth for twenty minutes.
Read more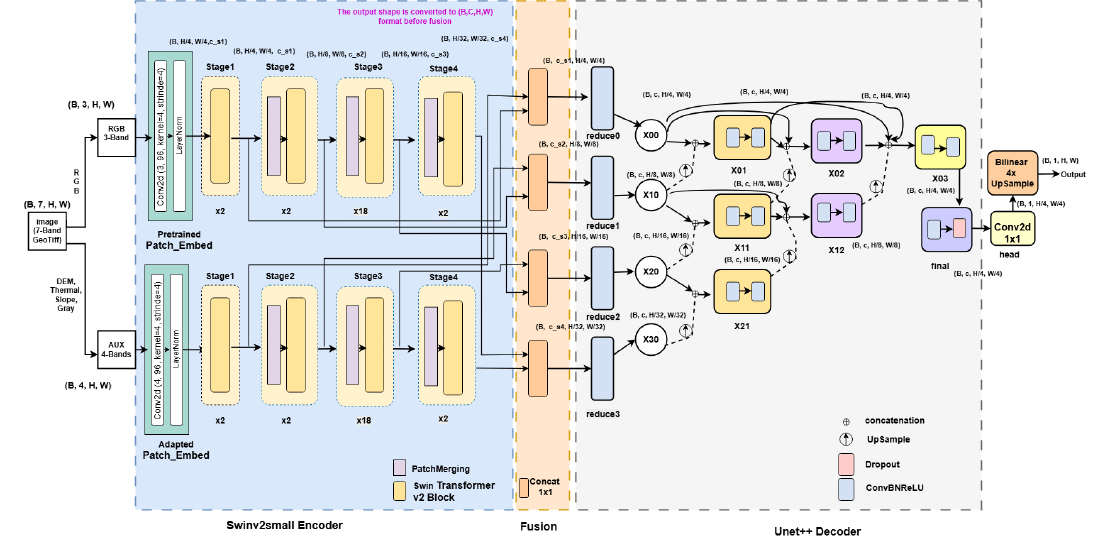
DualSwinFusionSeg: Multimodal Martian Landslide Segmentation via Dual Swin Transformer with Multi-Scale Fusion and UNet++
Mars has landslides. Just like on Earth, slopes collapse, dust and rock slide downhill, and the scars stay visible for a long time.
Read more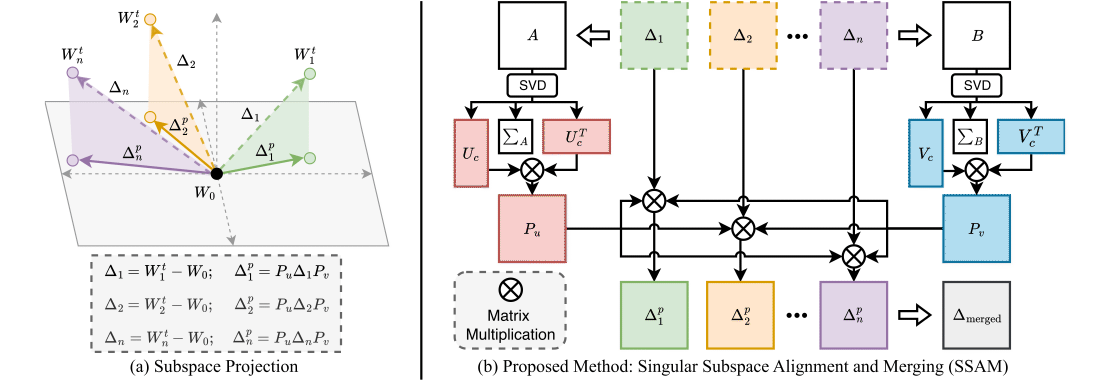
SSAM: Singular Subspace Alignment for Merging Multimodal Large Language Models
Imagine you have two AI assistants. One is really good at looking at pictures and talking about them. The other is really good at listening to sounds and talking about them.
Read more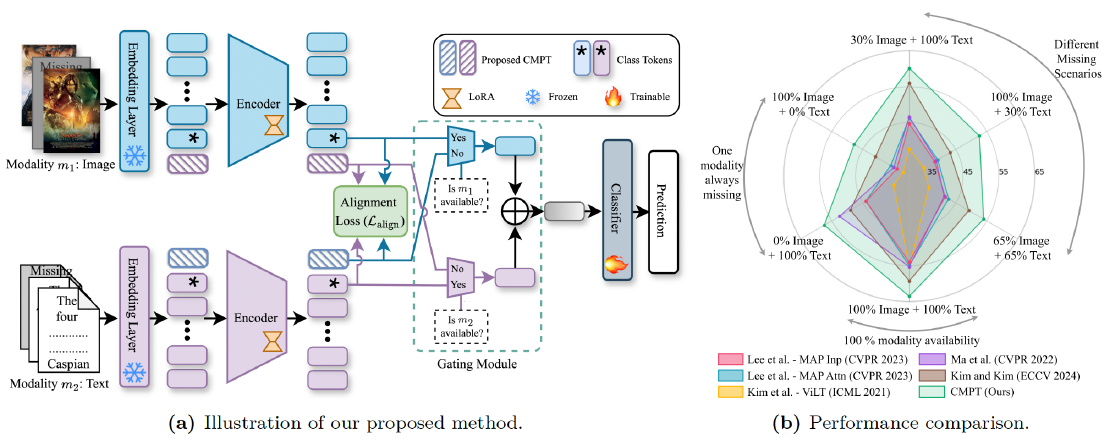
Robust Multimodal Learning via Cross-Modal Proxy Tokens
Imagine an AI designed to understand the world through multiple senses—like sight and hearing. It can identify a cat by both its picture (vision) and its “meow” (audio).
Read more